AMAX AI Factory Solutions Powered by NVIDIA Vera Rubin
NVIDIA® Vera Rubin Platforms for AI Infrastructure
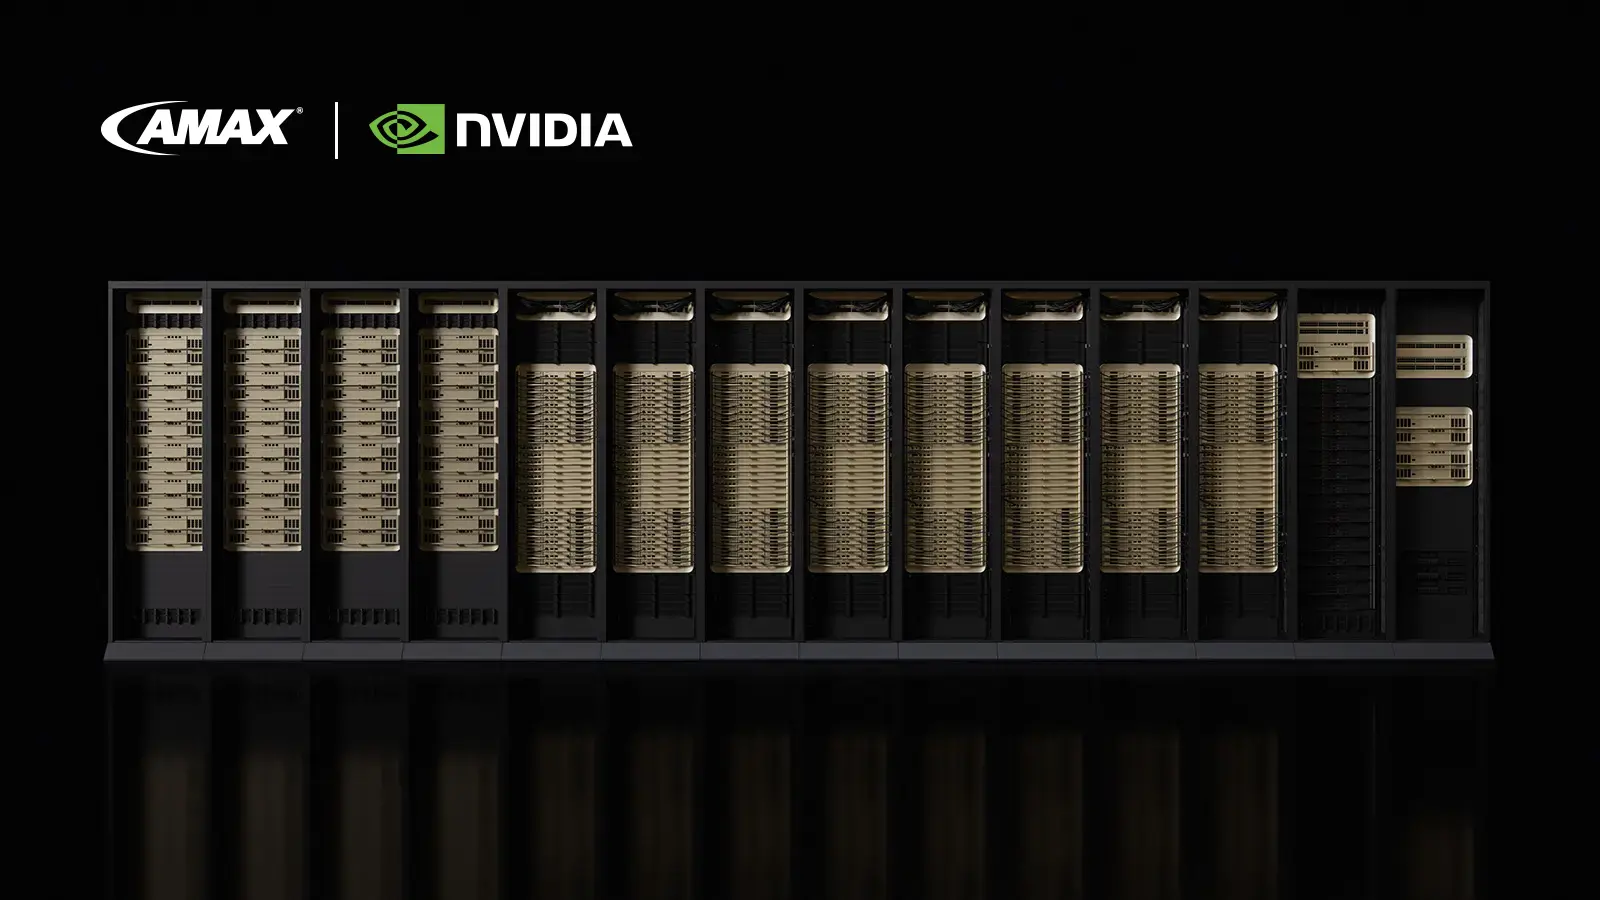
AMAX designs, builds, and deploys production AI infrastructure powered by NVIDIA DGX™ systems and NVIDIA HGX™ Rubin platforms. Our engineers bring together high-density accelerated computing, scale-up and scale-out networking, storage, liquid cooling, power planning, and deployment services for training, post-training, reasoning, agentic AI, and inference.
NVIDIA Rubin is available through turnkey DGX systems and partner-built platforms. AMAX works across both deployment models, from compact eight-GPU systems to complete rack-scale AI factories. NVIDIA MGX™ is a modular reference architecture for accelerated computing, helping system builders design future-compatible systems faster, reducing costs, accelerating time to market, and improving ROI.
Solution Brief Request a Quote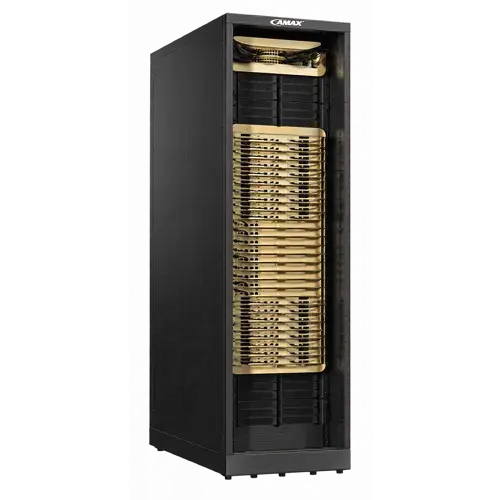 |
 |
 |
 |
|
|---|---|---|---|---|
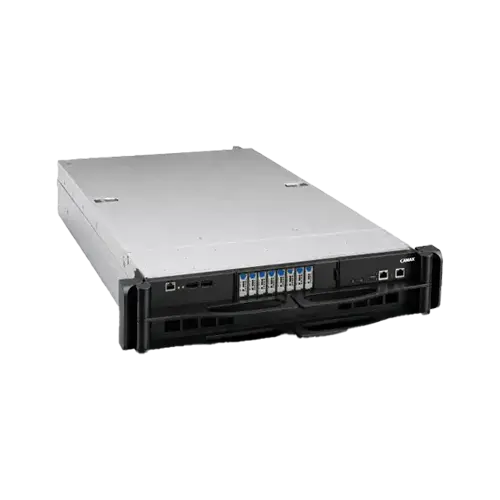
| NVIDIA DGX Vera Rubin NVL72 |
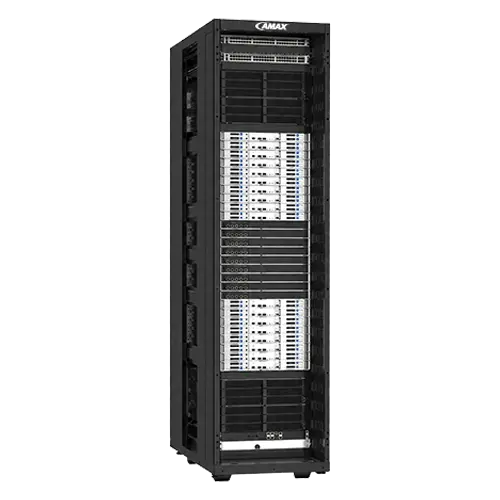
NVIDIA DGX Rubin NVL8 |
NVIDIA Vera Rubin NVL72 |
NVIDIA HGX Rubin NVL8 |
|
| Product category | NVIDIA DGX rack-scale; fully liquid-cooled rack-scale | NVIDIA DGX system; 2U liquid-cooled |
Rack-scale NVIDIA MGX platform; fully liquid-cooled rack-scale | Eight-GPU HGX platform for OEM server designs* |
| Best suited for | Gigascale training, post-training, reasoning, and inference | Enterprise training, inference, post-training, and agentic AI | Large AI factories requiring partner-built rack-scale infrastructure | Custom AI servers and clusters for agentic AI, analytics, and HPC |
| GPU and CPU | 72 NVIDIA Rubin GPUs and 36 NVIDIA Vera CPUs | 8 NVIDIA Rubin GPUs and 2 Intel Xeon 6776P processors | 72 NVIDIA Rubin GPUs and 36 NVIDIA Vera CPUs | 8 NVIDIA Rubin GPUs; x86 CPU configuration |
| GPU memory | 20.7 TB HBM4 with up to 1,400 TB/s bandwidth | 2.3 TB HBM4 with 176 TB/s bandwidth | 20.7 TB HBM4 with up to 1,400 TB/s bandwidth | 2.3 TB HBM4 with 176 TB/s bandwidth |
| AI performance | 3,600 PFLOPS NVFP4 inference; 2,520 PFLOPS NVFP4 training** |
400 PFLOPS NVFP4 inference; 280 PFLOPS NVFP4 training** |
3,600 PFLOPS NVFP4 inference; 2,520 PFLOPS NVFP4 training** |
400 PFLOPS NVFP4 inference; 280 PFLOPS NVFP4 training** |
| NVLink™ | Sixth-generation NVLink 260 TB/s total NVLink switch bandwidth |
Sixth-generation NVLink 28.8 TB/s total NVLink switch bandwidth |
Sixth-generation NVLink 260 TB/s total NVLink switch bandwidth |
Sixth-generation NVLink; 28.8 TB/s total NVLink switch bandwidth |
| Scale-up and Scale-out networking | NVIDIA ConnectX-9 and BlueField®-4; NVIDIA Quantum-X InfiniBand or NVIDIA Spectrum-X™ Ethernet | ConnectX-9 and BlueField-4; NVIDIA Quantum-X InfiniBand or NVIDIA Spectrum-X™ Ethernet |
ConnectX-9 and BlueField-4; NVIDIA Quantum-X InfiniBand or NVIDIA Spectrum-X™ Ethernet |
Up to 1.6 Tb/s; networking configuration defined by the server design |
| Software and operations | NVIDIA DGX OS, NVIDIA AI Enterprise, NVIDIA Mission Control™, and DGX support | NVIDIA DGX OS, NVIDIA AI Enterprise, NVIDIA Mission Control, and DGX support | Software and operational services depend on the partner-built system | Software, system management, and support depend on the OEM server configuration |
* * NVIDIA HGX™ Rubin NVL8 uses an x86 CPU baseboard. When paired with an NVIDIA Vera CPU, NVIDIA identifies the platform as NVIDIA HGX™ Vera Rubin NVL8.
** Dense specification. Preliminary information; all values are up to and subject to change.
From a Decade of Liquid Cooling to the Vera Rubin Generation
Since 2015, AMAX has developed liquid-cooled computing systems across thermal engineering, rack design, manufacturing, validation, and deployment. Today, AMAX operates a high-density liquid-cooled validation environment supporting up to 140 kW per rack, providing a production-scale environment for testing rack-level cooling, power, networking, system operation, and deployment readiness before equipment reaches the customer site.
10+ Years
Liquid-cooling engineering
Up to 140 kW/Rack
High-density validation capability
Rack-Level Validation
Compute • Network
Storage • Cooling
Power • Software
NPI → Production
Engineering • Build
Test • Manufacturing
Site Readiness
Facility assessment
Installation
Commissioning
This engineering foundation extends beyond the rack. AMAX applies the same system-level approach across compute, networking, storage, cooling, power, and operations to support complete Vera Rubin AI Factory deployments.
Built for the Full AI Factory
NVIDIA Vera Rubin extends beyond GPU compute to address data movement, networking, infrastructure processing, storage, security, power, cooling, and AI Factory operations. AMAX brings these infrastructure domains together at rack and cluster scale, supporting the transition from individual systems to complete production AI environments.
The NVIDIA Vera Rubin platform is built around seven chips and five purpose-built rack-scale systems, including NVIDIA Vera Rubin NVL72, the NVIDIA Vera CPU. Rack, NVIDIA Groq 3 LPX, NVIDIA BlueField-4 STX storage rack, and NVIDIA Spectrum-6 SPX Ethernet. NVIDIA Vera CPU Rack delivers dense CPU capacity for agentic AI, RL, and data processing, supporting 22.5K sandboxes at liquid-cooled AI factory scale.
Across the platform, compute, networking, storage, infrastructure processing, and CPU resources support pretraining, post-training, reinforcement learning, data processing, and real-time agentic inference at AI Factory scale.
Built for Continuous AI Factory Operations
Vera Rubin NVL72 combines rack-scale confidential computing, continuous health monitoring, intelligent fault handling, serviceable compute and switch trays, and fine-grained infrastructure telemetry. These capabilities support long-running training jobs and persistent inference services where predictable operation and service access are critical.
AMAX incorporates these platform capabilities into deployment planning, monitoring design, commissioning, service procedures, and lifecycle operations.
Massive Efficiency Gains in AI Inference and Training
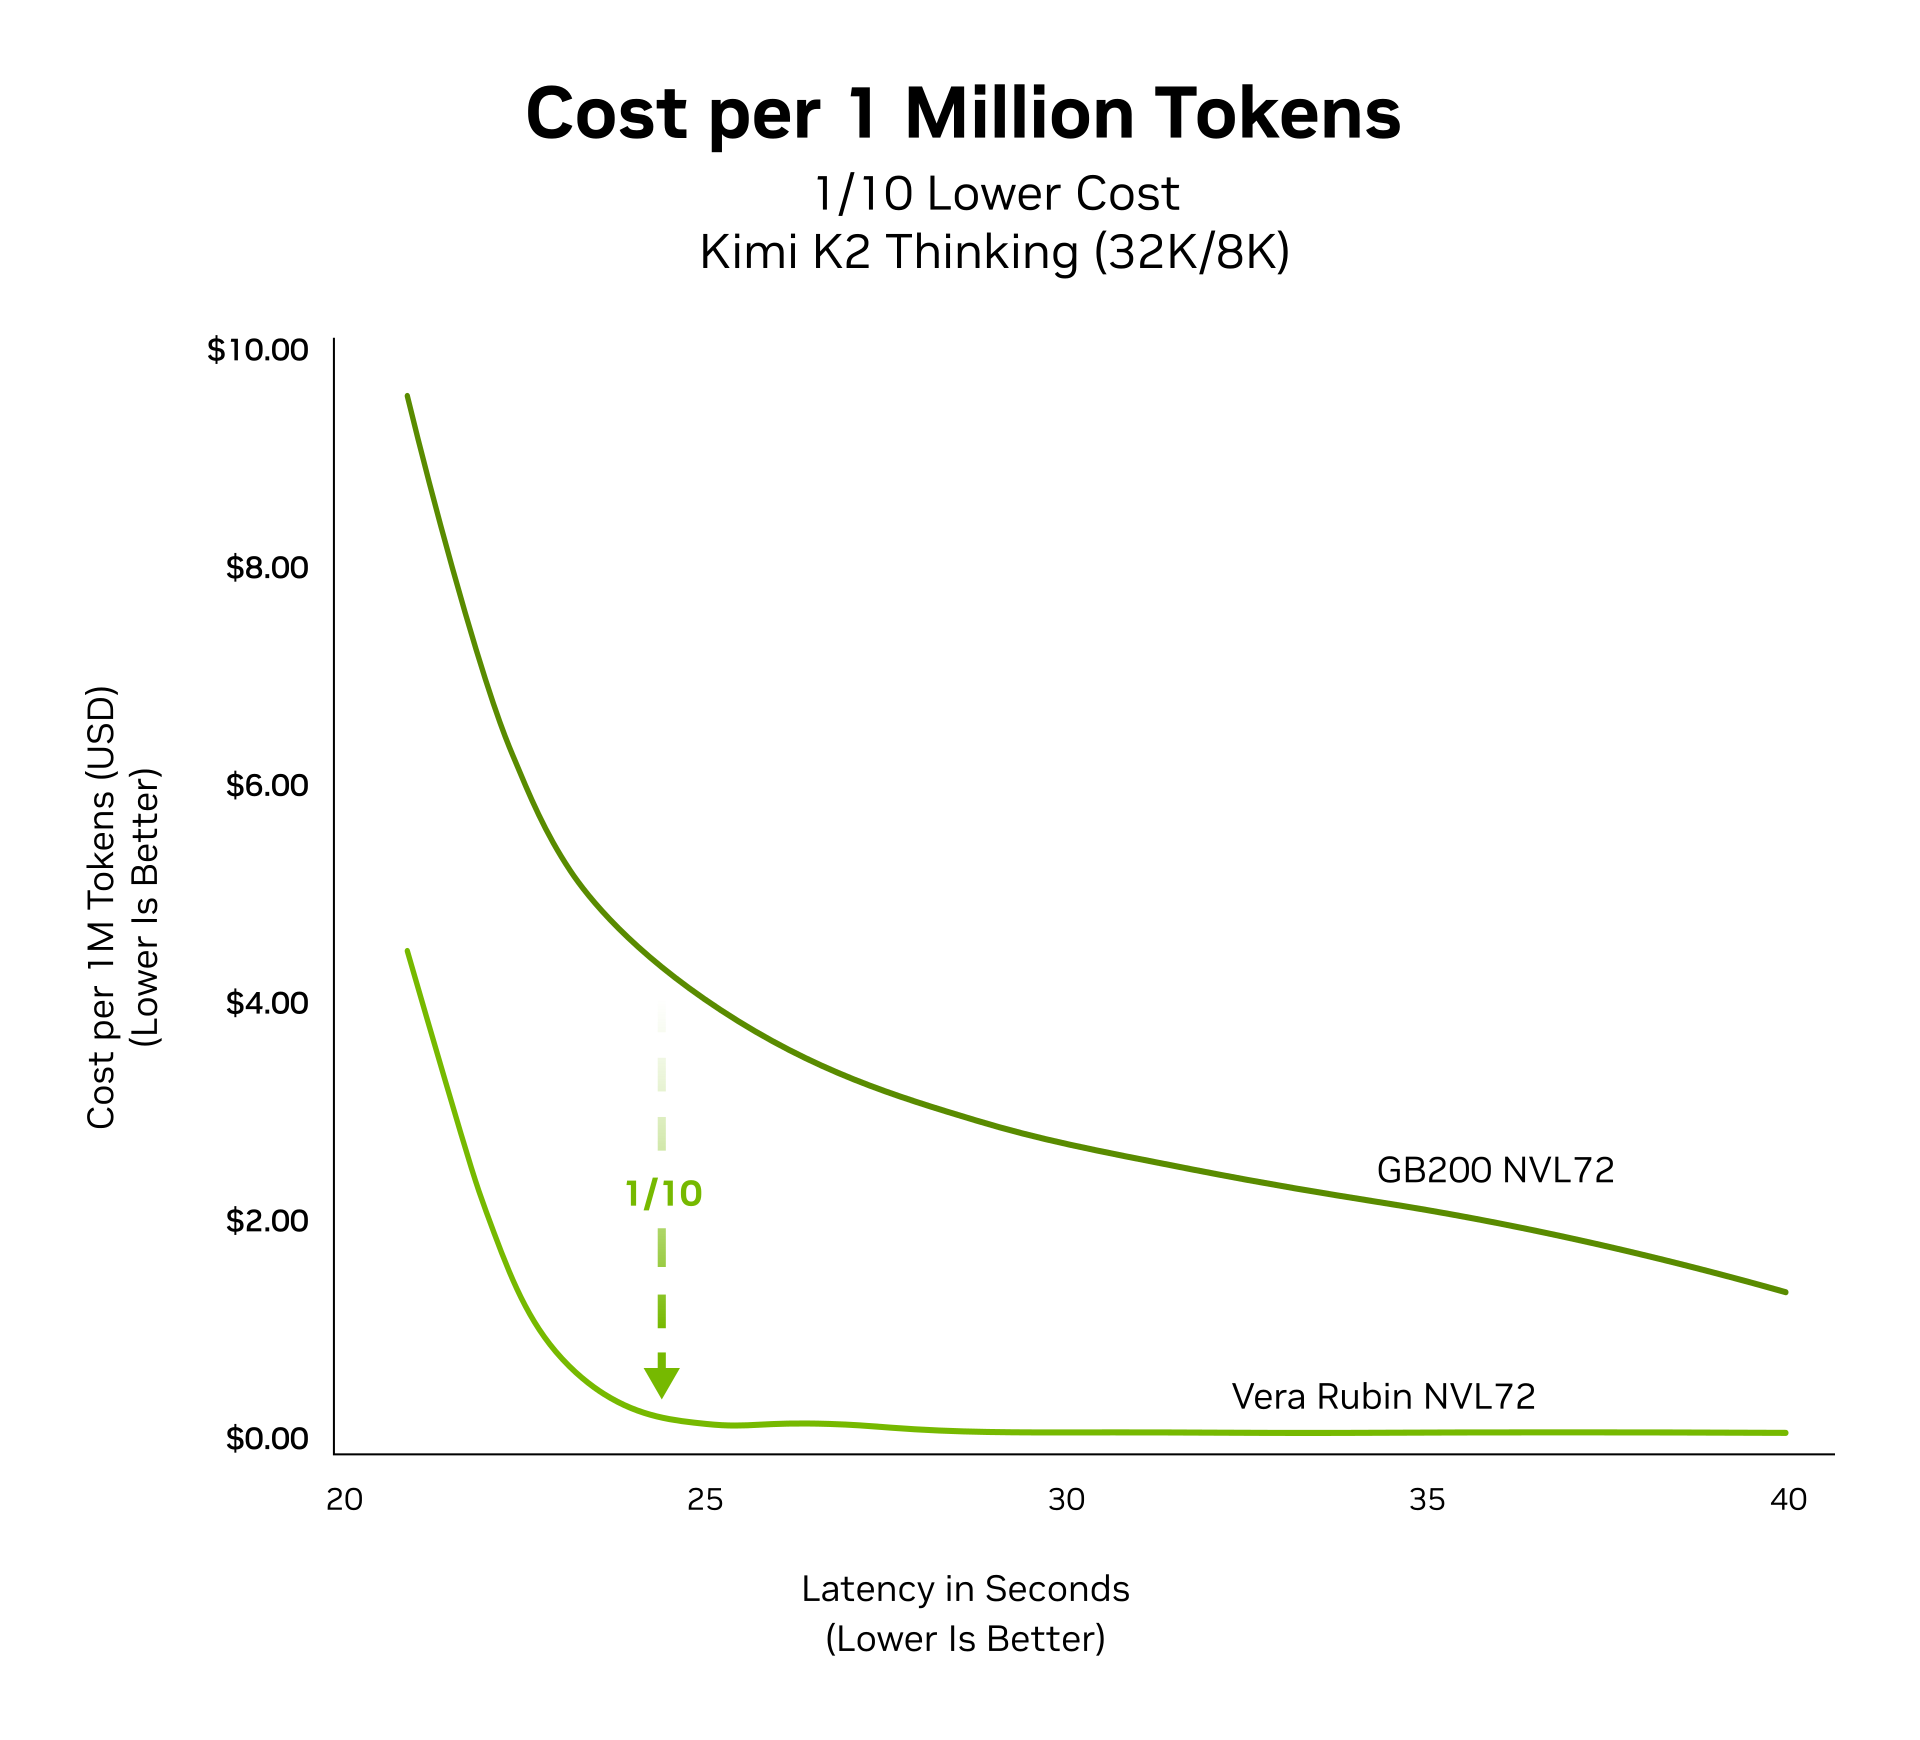
NVIDIA Vera Rubin NVL72 delivers one-tenth the cost per million tokens compared to NVIDIA GB200 NVL72 for highly interactive, deep reasoning agentic AI.
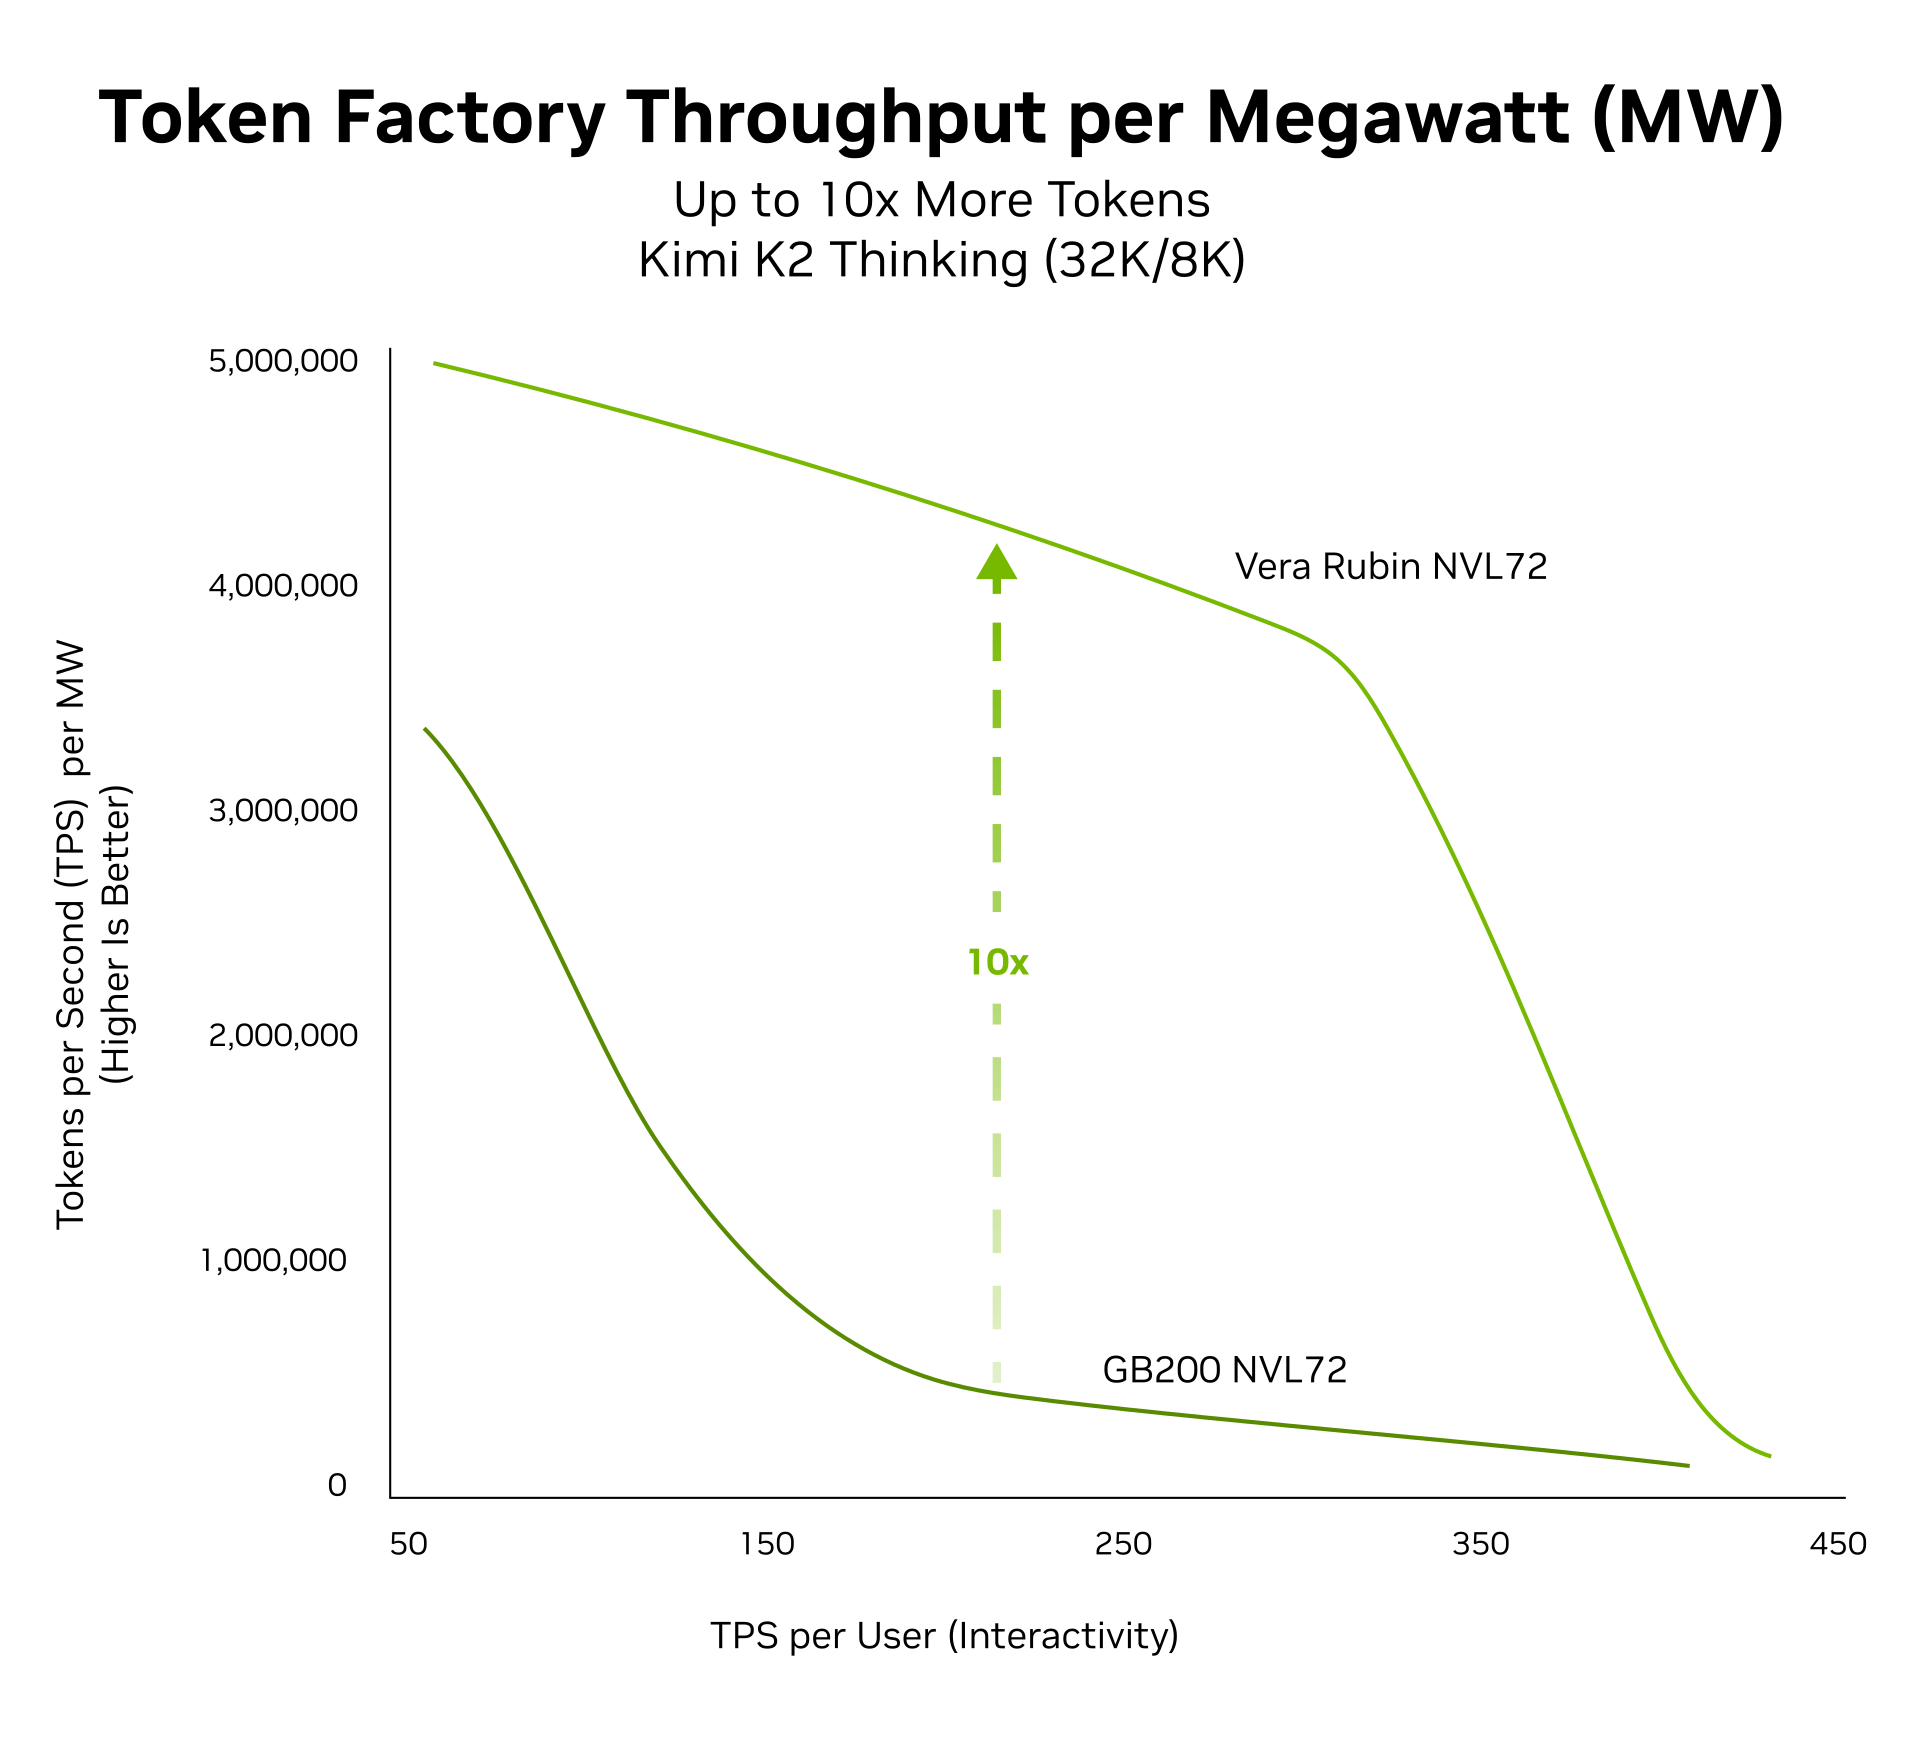
NVIDIA Vera Rubin NVL72 delivers up to 10x more tokens per megawatt than NVIDIA GB200 NVL72, scaling intelligence within the same power footprint.
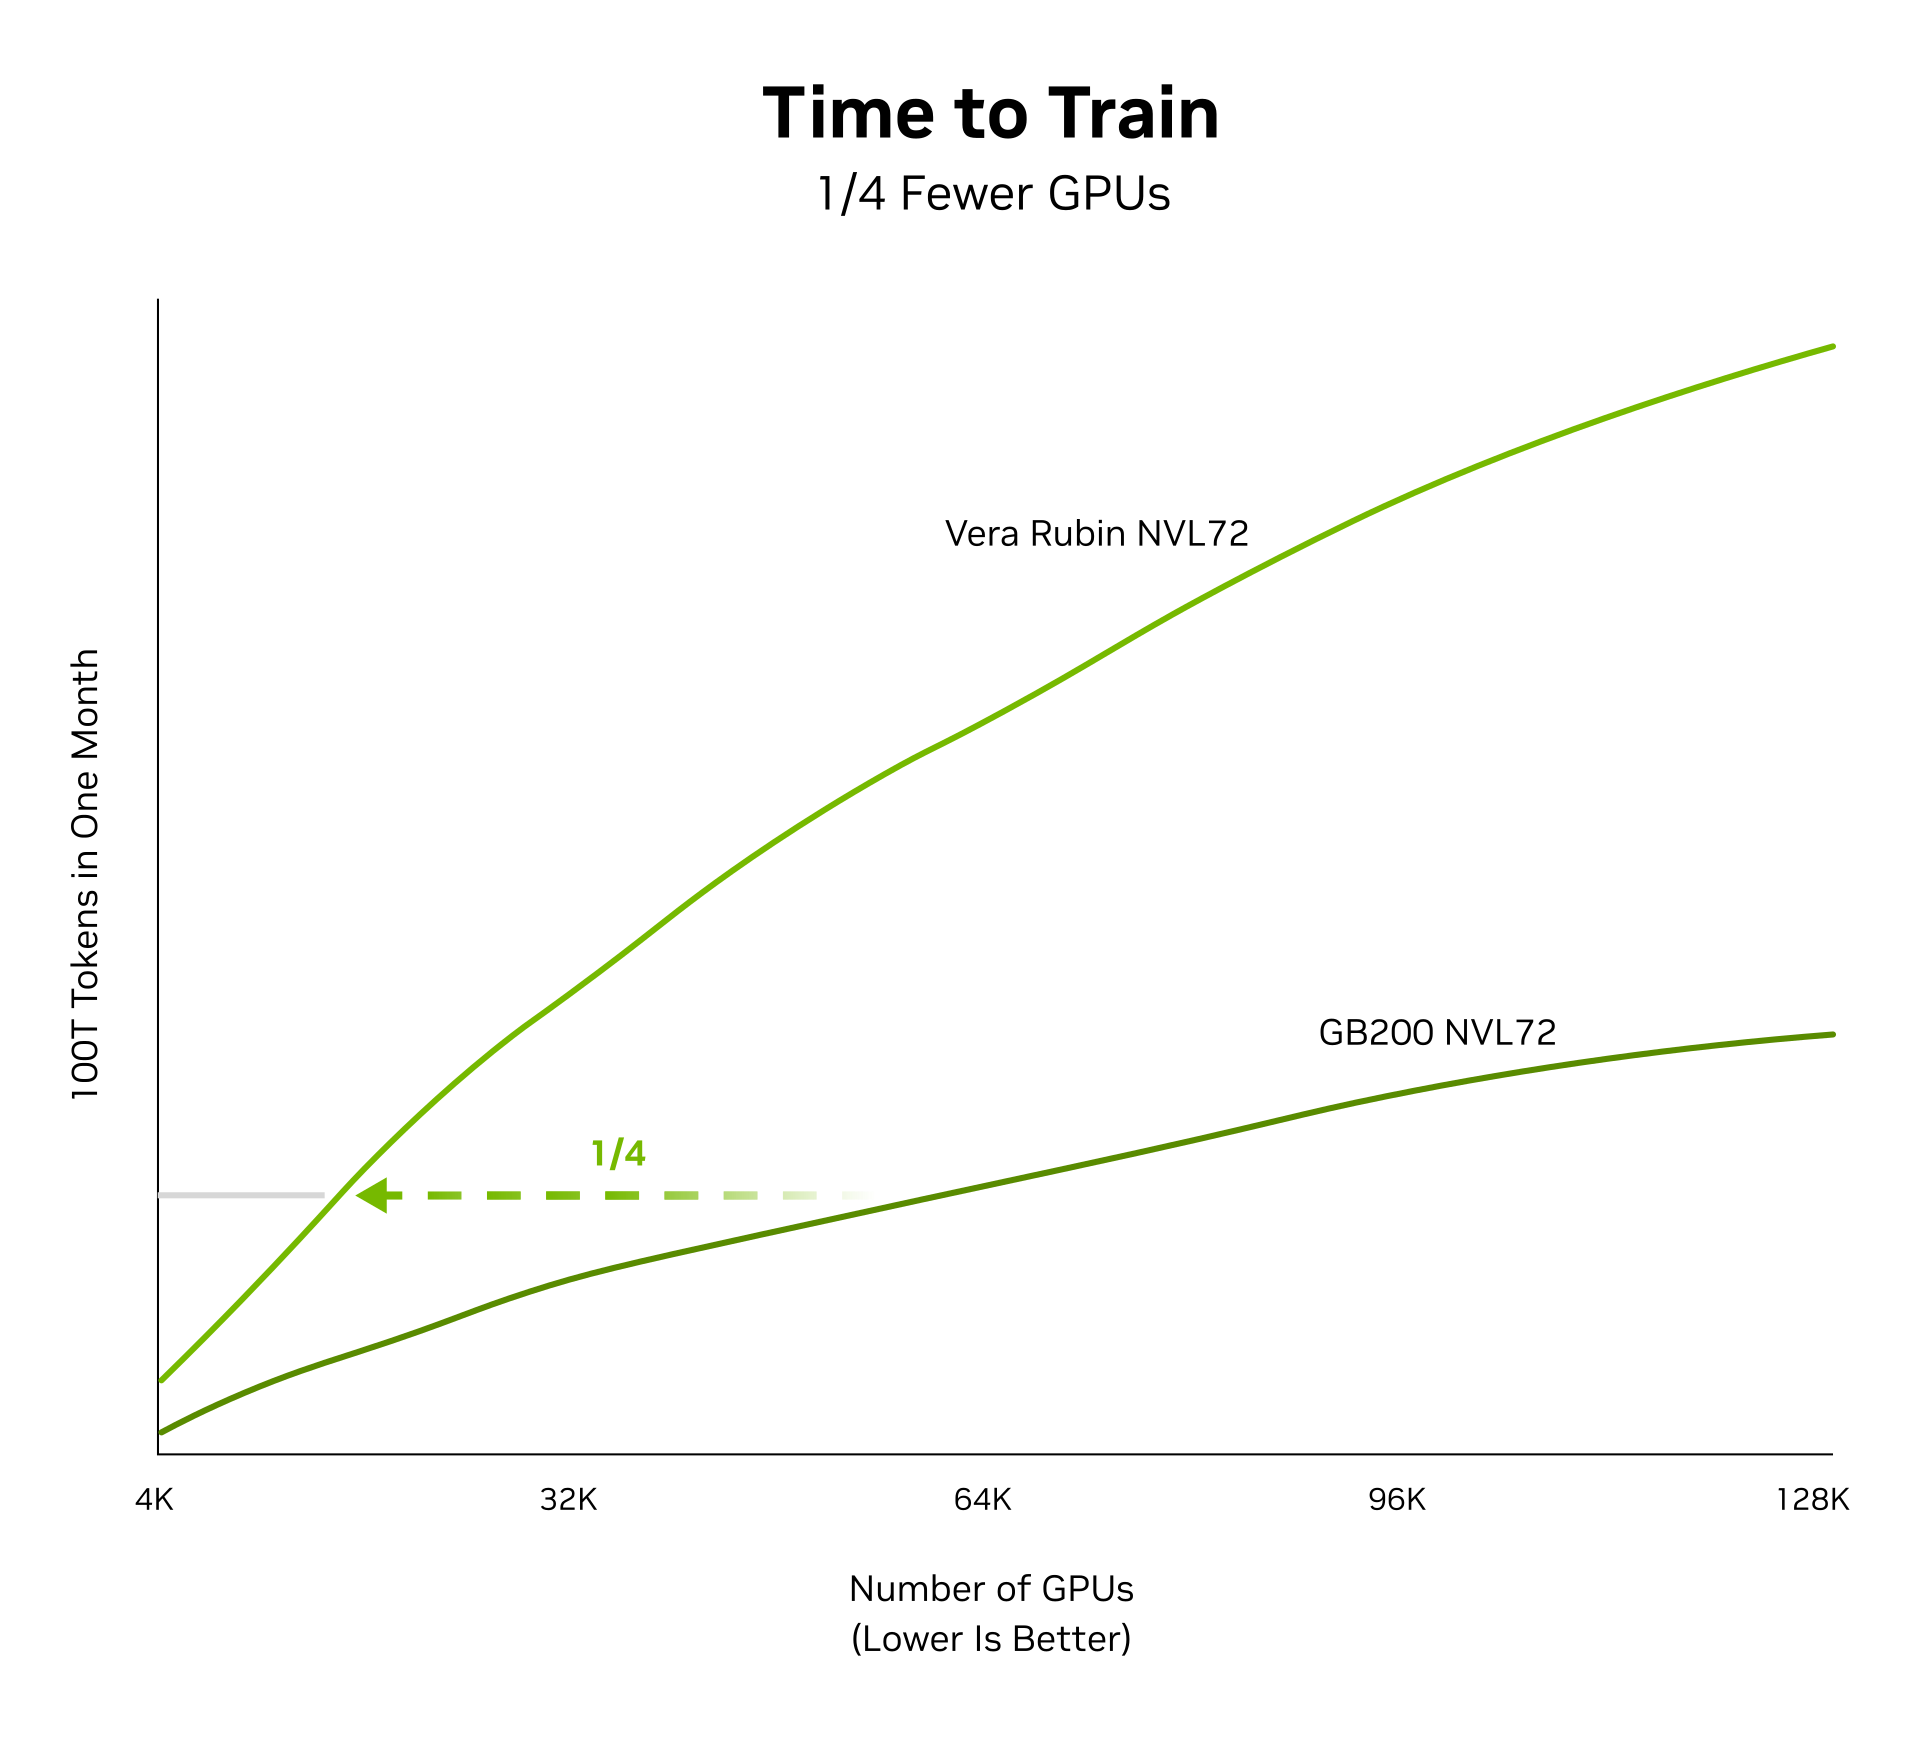
In NVIDIA’s projected comparison, Vera Rubin NVL72 trains a 10-trillion-parameter mixture-of-experts model on 100 trillion tokens using one-fourth the number of GPUs required by NVIDIA GB200 NVL72 within a fixed one-month training period.
When paired with NVIDIA Groq 3 LPX™, Vera Rubin NVL72 delivers up to 35x higher throughput per megawatt for trillion-parameter models, supporting large context windows and low-latency agentic AI experiences.
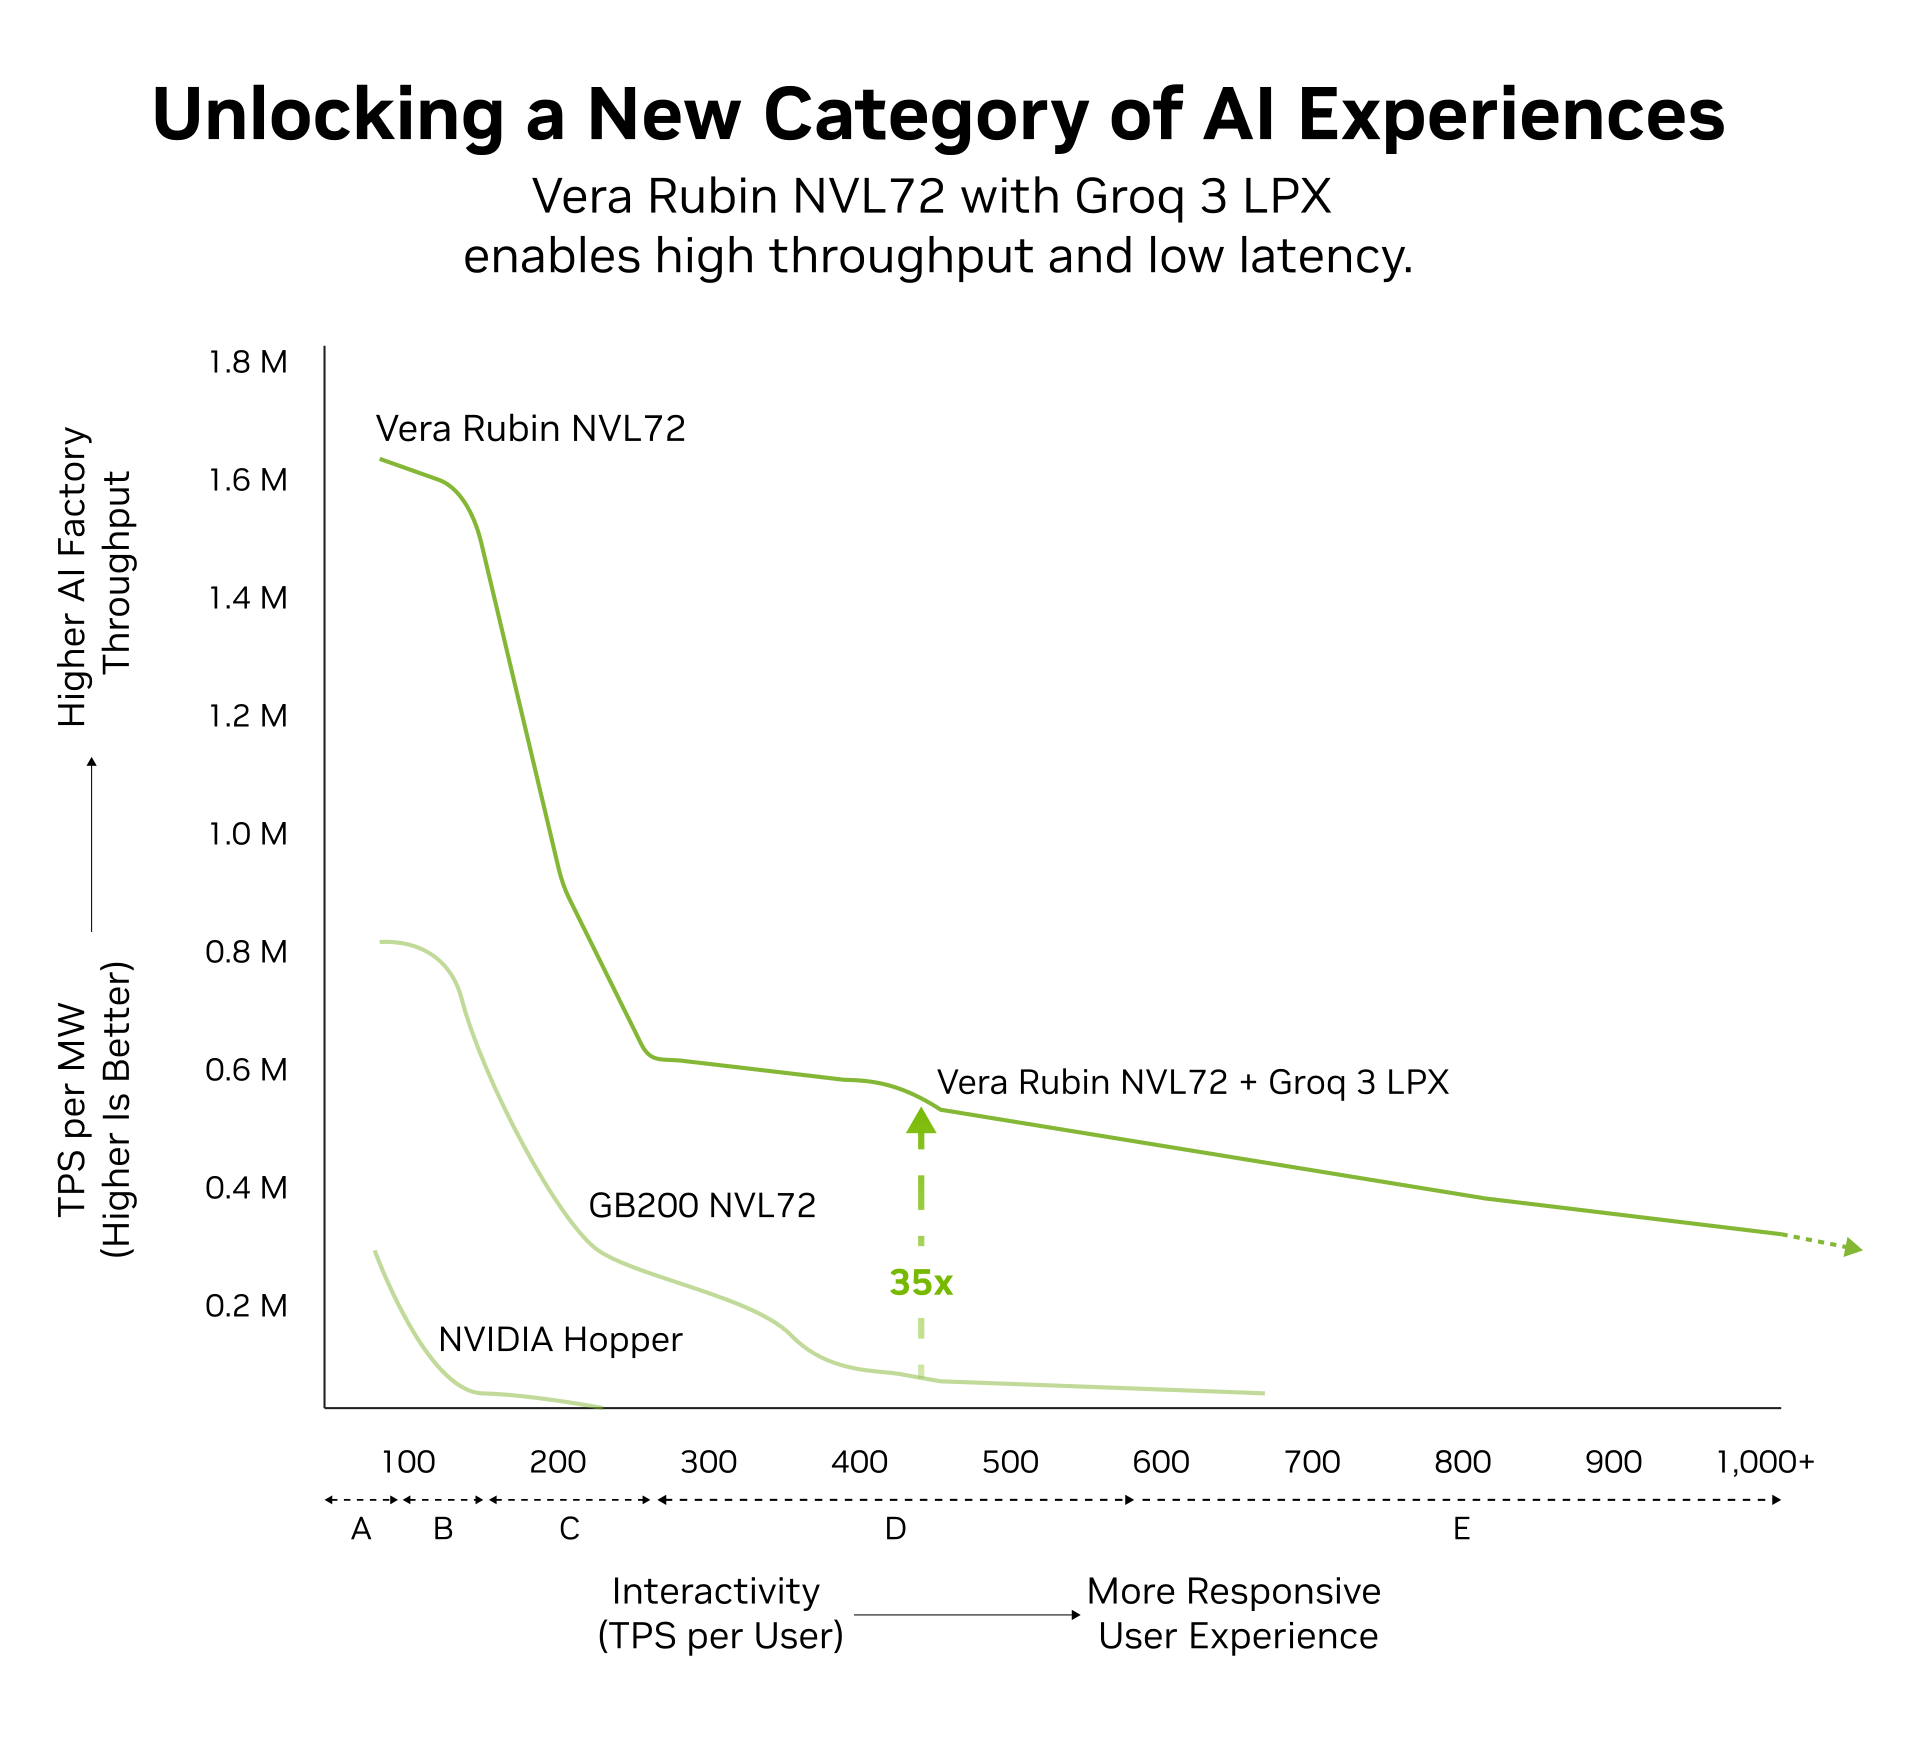
Performance results are projected and subject to change. Results vary by model, precision, context length, latency target, software configuration, and system configuration. Comparisons are based on NVIDIA-published workload assumptions.
Information Source: https://www.nvidia.com/en-us/data-center/vera-rubin-nvl72/
Why AMAX for Rubin-Based AI Infrastructure
Deploying Rubin-based infrastructure requires coordination across computing, networking, storage, power, cooling, software, and facility operations. AMAX provides system-level engineering from initial capacity planning through production deployment.
Liquid-Cooling Readiness
Assess facility water quality, supply temperature, flow, pressure, CDU placement, heat rejection, monitoring, and service access.
Workload and Capacity Planning
Size GPU, CPU, memory, networking, and storage resources around training, reasoning, post-training, and inference requirements.
Rack and Cluster Engineering
Design system layouts, fabric topology, storage architecture, power distribution, and expansion capacity.
Factory Build and Validation
Assemble, cable, configure, burn in, and validate systems before deployment.
On-Site Deployment and Commissioning
Coordinate delivery, installation, network bring-up, cooling verification, and acceptance testing.
Lifecycle Services
Support system health, infrastructure telemetry, service planning, capacity expansion, component replacement, and platform updates.